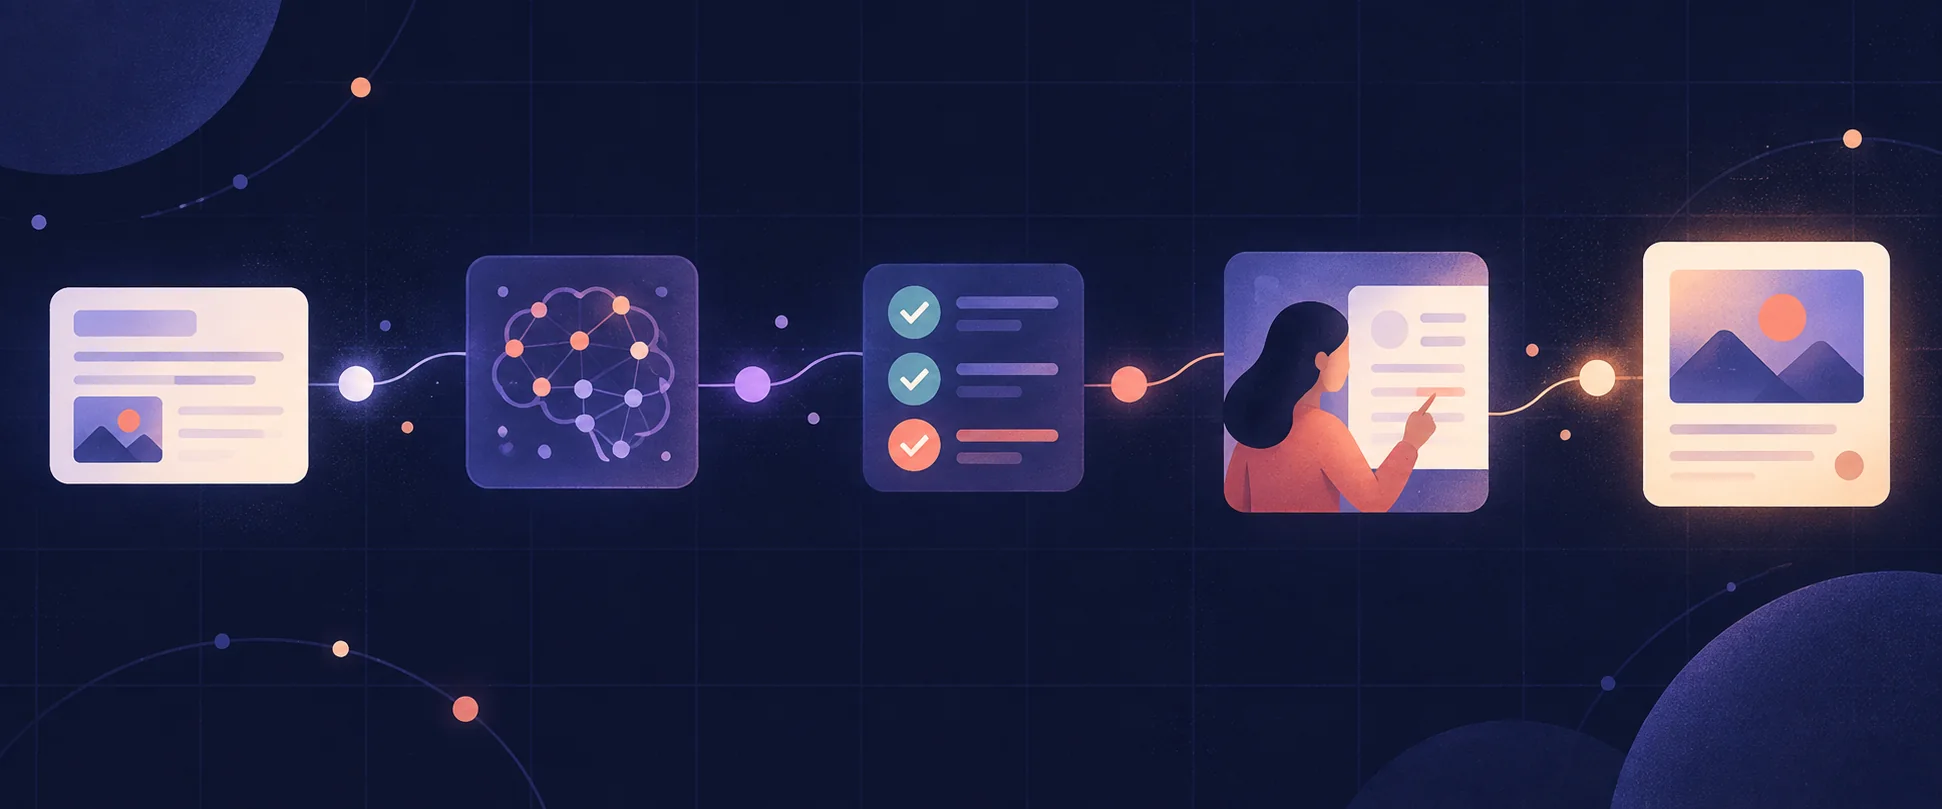
When to use AI in a data pipeline
A data pipeline does not need AI at every step. Models are useful where the input needs interpretation: classifying an open-ended request, extracting a field from varied language, or summarizing a document.
Mark the uncertain operation
Suppose your pipeline receives expenses. Reading a merchant description may require interpretation. Adding amounts, checking a required currency, and grouping by month usually do not. Asking a model to perform all four operations makes it harder to identify the source of an error. It also spends model calls on work that ordinary code can perform exactly.
- 1Draw the transformation from source record to…Draw the transformation from source record to destination record.
- 2Mark only the steps requiring language or…Mark only the steps requiring language or document interpretation.
- 3Add deterministic validation immediately after each model…Add deterministic validation immediately after each model output.
Try it on a small example
- Draw the transformation from source record to destination record.
- Mark only the steps requiring language or document interpretation.
- Add deterministic validation immediately after each model output.
What to verify
Test whether a simpler rule handles a subset of records without changing the intended behavior. For example, an exact vendor mapping can handle familiar merchants while unfamiliar ones go to classification. Baleybots pipelines separate sources, processor programs, and destinations. Use that separation to inspect the interpreted fields before a write. If a model step cannot explain its role in the output contract, consider removing it.
Product details checked against the Pipeline architecture on October 4, 2026. These guides describe documented behavior; availability depends on your account and the deployed service. Baleybots is in invite-only beta.